My take on Anthropic's Scion: git has to adapt, but not like this
Anthropic replaced git for their monorepo. I work with very large repos, and here is what I think carries over and what doesn't.
- 3 min read
- GitVersion ControlAIClaude Code
Anthropic published a piece on redesigning source control, and it's worth reading in full. The short version: merges to their monorepo went from around 2,500 a day in May to over 30,000 a day by September, because Claude was writing most of the code. Git, which assumes every clone is a complete offline copy, became the bottleneck. So a small team built Scion, a centralised system with always-online clients, and moved the repo over in about five months.
I work with a very large repo most days, so I read it with some experience of the pain. I think the diagnosis is right and a lot of the solution is not for most of us.
#The diagnosis is right
Git was designed for people on laptops who might be offline. Agents and CI jobs are always online and they don't need a full copy of history. For a repo at serious size, cloning, checking out and keeping mirrors fresh becomes a daily cost, and the usual workarounds (shallow and sparse clones, mirrors) add their own operational weight.
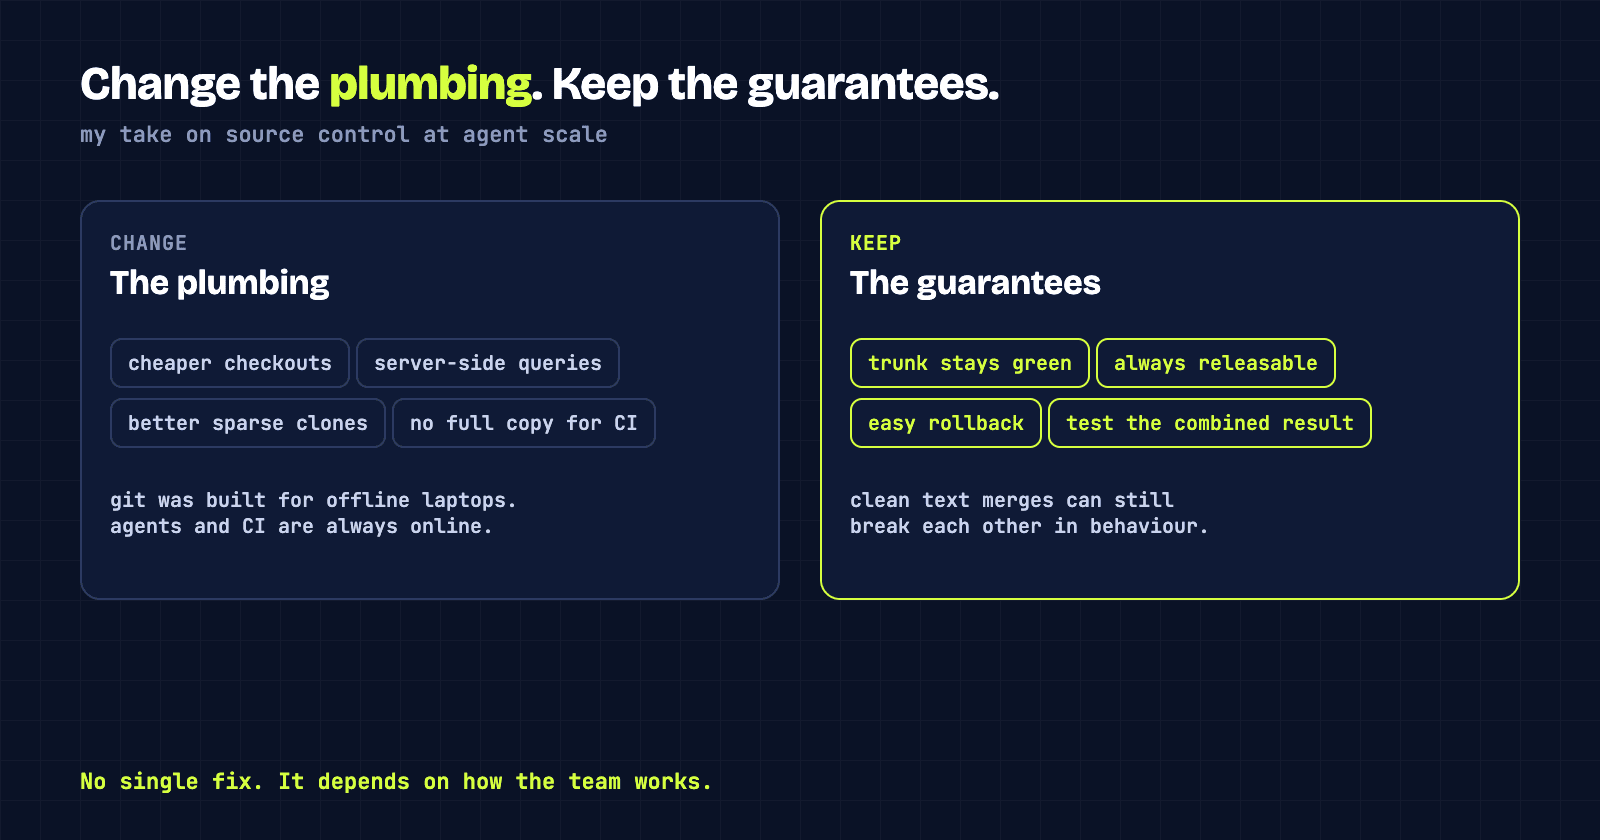
I think git does need to adapt. Server-side operations, better partial and sparse checkouts and cheaper checkouts for automated jobs all seem like the direction. The article's authors say much the same: they suggest taking Scion's ideas back to git.
#It also assumes a lot
Scion is a bespoke system built by a company that makes the models and doesn't have to think about token cost. Seven people built it, with Claude doing a great deal of the work. That's not a template most teams can follow, and I'd be wary of anyone treating it as one.
#Keeping main safe is the hard part
The piece I'd push back on is the change in workflow. The article notes that merge queues with global locks don't suit agent-scale development, so they rely on testing after merge and before deploy instead.
I understand why. But a trunk that is always green, and always safe to release from, is a property the industry spent decades reaching for. It gives you release confidence, easy rollbacks and a clear answer to "what's in production?". Giving it up means every team that follows needs something equally strong to replace it.
The harder problem underneath is semantic conflicts. Two changes that merge cleanly in text and break each other in behaviour. A tool can't see those by diffing. You catch them by running the right tests against the combined result.
#Agents fixing merges won't scale
A tempting answer is to let the AI resolve conflicts as they come. On a small repo that works fine. On a very large one with heavy traffic it turns into a treadmill, with agents repeatedly fixing what other agents just broke, each retry costing time and tokens. I don't think that's viable as the primary strategy.
I also don't think there's a single fix. What a big repo needs depends on how its teams work: how often they merge, how they test, how they release. The right answer for one will be wrong for another.
#What I'd do
Keep the guarantees, change the plumbing. Make checkouts cheaper and queries server-side, keep a protected, deployable trunk, and invest in testing the combined result. That's less exciting than a new version control system, and I suspect it's what most teams actually need.